Ai And Machine Learning
Origin and history
The foundational concepts for artificial intelligence and machine learning emerged from academic conferences in the United States and the United Kingdom during the mid-20th century. The field was formally established as an academic discipline at a workshop held at Dartmouth College in the United States in the 1950s. Early research focused on symbolic approaches and problem-solving algorithms, with funding often linked to defense and space exploration initiatives of that era. The term "machine learning" was coined later, with its core ideas about algorithms improving through experience gaining prominence in the 1980s and 1990s. The development of key theoretical frameworks, such as neural networks and statistical learning theory, occurred across multiple decades through international academic collaboration. The practical application of these technologies on a commercial scale, however, required the concurrent development of sufficient computational power and large-scale digital data collection, which materialized decades after the initial theoretical work.
What it is for
Artificial intelligence is a broad field of computer science aimed at creating systems capable of performing tasks that typically require human intelligence. Machine learning is a predominant subset of AI focused on developing algorithms that can learn patterns and make predictions from data without being explicitly programmed for every scenario. These technologies are used for automating complex decision-making processes, such as credit scoring or fraud detection in financial services. They enable the analysis of vast datasets to identify trends and insights that are impractical for humans to discern manually, as seen in genomic sequencing or climate modeling. In consumer applications, they power recommendation systems, natural language processing for virtual assistants, and computer vision for image recognition. Fundamentally, they serve to augment or automate analytical and cognitive tasks across virtually every sector, from logistics optimization to medical diagnosis support.
Overview
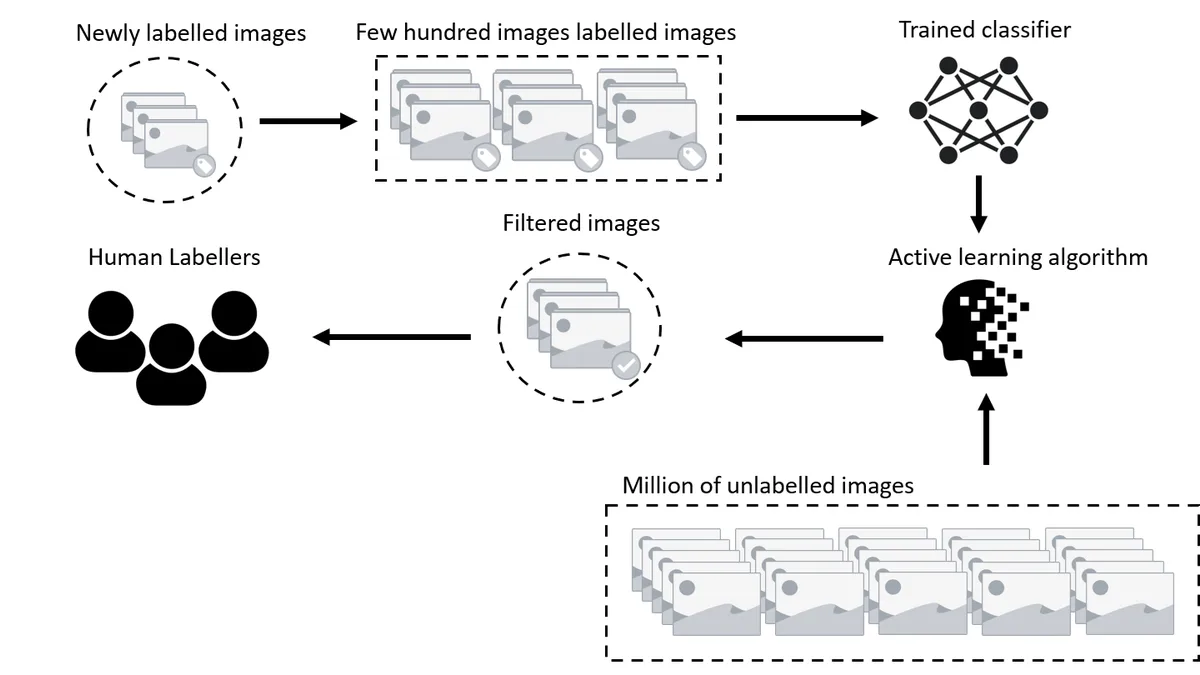
Artificial intelligence encompasses a wide spectrum of approaches, from rule-based expert systems to complex machine learning models. Machine learning itself is typically categorized into supervised learning, unsupervised learning, and reinforcement learning, each with distinct methodologies and applications. The current dominant paradigm is based on data-driven models, particularly deep learning, which utilizes multi-layered artificial neural networks. These systems operate by processing input data through mathematical models with adjustable parameters that are iteratively refined during a training phase. The performance of a machine learning model is heavily dependent on the quality, quantity, and relevance of the training data provided to it. Successful implementation requires a pipeline encompassing data acquisition, cleaning, model selection, training, validation, and ongoing monitoring, rather than being a singular act of software development.
What to know
Founders must understand that building an AI/ML-driven company is often primarily a data acquisition and infrastructure challenge, not solely a algorithmic one. Securing proprietary, high-quality, and legally-obtained datasets is frequently a more significant competitive moat than the choice of model architecture. The development cycle is iterative and experimental, requiring a tolerance for failure and a rigorous process for testing model performance against real-world outcomes. Founders should be aware of the substantial computational costs associated with training sophisticated models, which directly impacts burn rate and infrastructure decisions. Ethical considerations, including algorithmic bias, fairness, transparency, and privacy, are not afterthoughts but core design constraints that must be integrated from the outset. Furthermore, regulatory landscapes for AI applications are evolving rapidly across jurisdictions, adding a layer of compliance risk that must be actively managed.
Common questions
A common question is whether a startup truly needs machine learning or if a simpler, rule-based solution would suffice, given the added complexity and cost. Founders often ask what the minimum viable dataset size is to build a functional model, though the answer is highly problem-dependent and relates more to data representativeness than sheer volume. Many inquire about the talent requirement, specifically whether they need to hire PhD-level researchers or can utilize existing engineering talent and cloud-based AI services. Questions regarding intellectual property frequently arise, particularly concerning whether a model's weights can be protected and if training on publicly available data carries legal risk. Founders commonly seek to understand the ongoing maintenance burden of ML systems, which includes concept drift monitoring and model retraining cycles. There is also frequent confusion about the distinction between prototyping a model in a controlled environment and deploying a reliable, scalable inference system in production.
Pros and cons
A significant advantage is the potential to automate complex, scalable decision-making and uncover non-intuitive insights from data, creating defensible products. A major con is the high risk of technical failure; models may perform well on test data but fail in production due to unseen data distributions or changing real-world conditions. Founders often underestimate the long-term resource drain of maintaining and updating models, leading to "technical debt" that can cripple a product. A common mistake is pursuing an ML solution for a problem that lacks a clear objective function or sufficient, reliable data, resulting in wasted resources. Those who regret the choice are typically founders who adopted the technology for its hype rather than a clear product-market fit, finding themselves with an expensive, fragile system that offers no real user advantage. The "black box" nature of many powerful models can also create user trust issues and regulatory hurdles, becoming a severe business liability.
Who it suits
This path suits founders with deep domain expertise in a specific industry who have identified a high-value, data-rich problem that is intractable with conventional software. It is appropriate for technical founders who have direct experience with the ML development lifecycle and its pitfalls, or who have secured co-founders with that specific competency. It suits ventures where the core intellectual property and competitive advantage are inherently tied to proprietary data or unique algorithmic insights derived from data. Founders must be comfortable with a longer, more research-oriented development timeline and have access to significant capital, as the burn rate for talent and compute is high. It is less suitable for founders seeking rapid, lean iterations or those operating in domains with strict explainability requirements but low tolerance for the opaque reasoning of complex models. Ultimately, it suits those who view the technology as a fundamental enabler of their product vision, not as a marketing feature.